Needed Some SQL
Ran into a minor hiccup while performing some exploratory data analysis. The type of my columns was wrong. This is the kind of thing I want fixed before Python, R, or Julia touch the dataset. This is the kind of thing that would be suited for SQL.
I have used MySQL for a different task that involves frequent updating. DuckDB is more suited for static data analysis. That ended up driving the choice of DuckDB. The CLI outputs are excellent. There are integrations available for Python, R, and Julia.
Comparison between DuckDB and MySQL
| Basis | DuckDB | MySQL/PostgreSQL |
|---|---|---|
| Primary purpose | Analytics | Operational applications |
| Server required | No | Usually yes |
| SQL | Yes | Yes |
| Reads CSV directly | Excellent | Not the normal workflow |
| Reads Parquet directly | Excellent | Not the normal workflow |
| Analytical queries | Excellent | Good, but different emphasis |
| Large aggregations | Excellent | Good |
| Joins | Excellent | Excellent |
| Transactions / concurrent applications | Not its focus | Excellent |
| Web applications | Not its focus | Excellent |
| Data science | Excellent | Useful |
Workflow
Here is the general idea around using DuckDB.
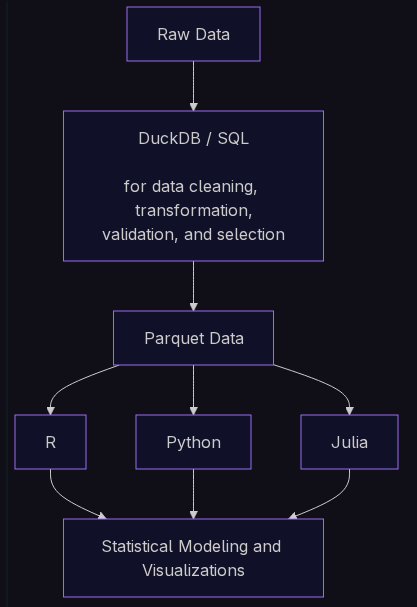
Processed Data
Below is an example of processing data. The “penguins.csv” file has numerical columns typed as string. This is what CAST(... AS DOUBLE/INTEGER) fixes. The NULLIF(..., 'NA') replaces ‘NA’ with NULL. The processed dataset is stored as “penguins.parquet” (it needed to be moved to the appropriate location).
COPY ( SELECT species, island,
        CAST(NULLIF(bill_length_mm, 'NA') AS DOUBLE) AS bill_length_mm,
        CAST(NULLIF(bill_depth_mm, 'NA') AS DOUBLE) AS bill_depth_mm,
        CAST(NULLIF(flipper_length_mm, 'NA') AS INTEGER) AS flipper_length_mm,
        CAST(NULLIF(body_mass_g, 'NA') AS INTEGER) AS body_mass_g,
        sex
        FROM 'penguins.csv'
    )
         TO 'penguins.parquet'
         (FORMAT PARQUET);
Integration
For Python:
import duckdb
con = duckdb.connect()

df = con.execute("""
    SELECT
        species,
        AVG(body_mass_g) AS mean_body_mass
    FROM 'data/processed/penguins.parquet'
    GROUP BY species
""").fetchdf()
For R:
library(DBI)
library(duckdb)
con = dbConnect(duckdb())

penguins = dbGetQuery(con, "
    SELECT
        species,
        AVG(body_mass_g) AS mean_body_mass
    FROM 'penguins.parquet'
    GROUP BY species
")
For Julia:
using DuckDB
con = DuckDB.DB()
df = DuckDB.execute(
    con,
    """
    SELECT species, AVG(body_mass_g)
    FROM 'penguins.parquet'
    GROUP BY species
    """
)